MilleMiglia: A Realistic Instance Generator for Middle-Mile Logistics
MilleMiglia is a generator that produces realistic middle-mile logistics instances for benchmarking and research. This guide explains what it creates, why realism matters for routing and consolidation problems, and how practitioners can use generated instances to test algorithms before deploying them on live freight networks.
Tags
Quick summary
MilleMiglia is a generator that produces realistic middle-mile logistics instances for benchmarking and research. This guide explains what it creates, why realism matters for routing and consolidation problems, and how practitioners can use generated instances to test algorithms before deploying them on live freight networks.
MilleMiglia: A Realistic Instance Generator for Middle-Mile Logistics
Optimization research lives or dies by its test instances. A vehicle-routing heuristic that looks excellent on a tidy set of randomly scattered points can behave very differently once demand clusters along a highway corridor, drivers hit hour-of-service limits, and depots are not interchangeable. Google Research has published MilleMiglia, described as a realistic instance generator for middle-mile logistics. This article explains what that class of tool is for, how to stand up a working environment around it, how to think about configuration and usage, and — just as importantly — where the public evidence stops and engineering judgement begins.
The primary source for everything factual below is the Google Research blog post at <https://research.google/blog/millemiglia-a-realistic-instance-generator-for-middle-mile-logistics>. The referenced source record carries the timestamp 2026-09-18T17:46:09.000Z. Where I describe domain practice, configuration knobs, or validation workflow, I say so explicitly and treat it as interpretation rather than as a documented feature.
Why Middle-Mile Logistics Needs Its Own Instance Generator
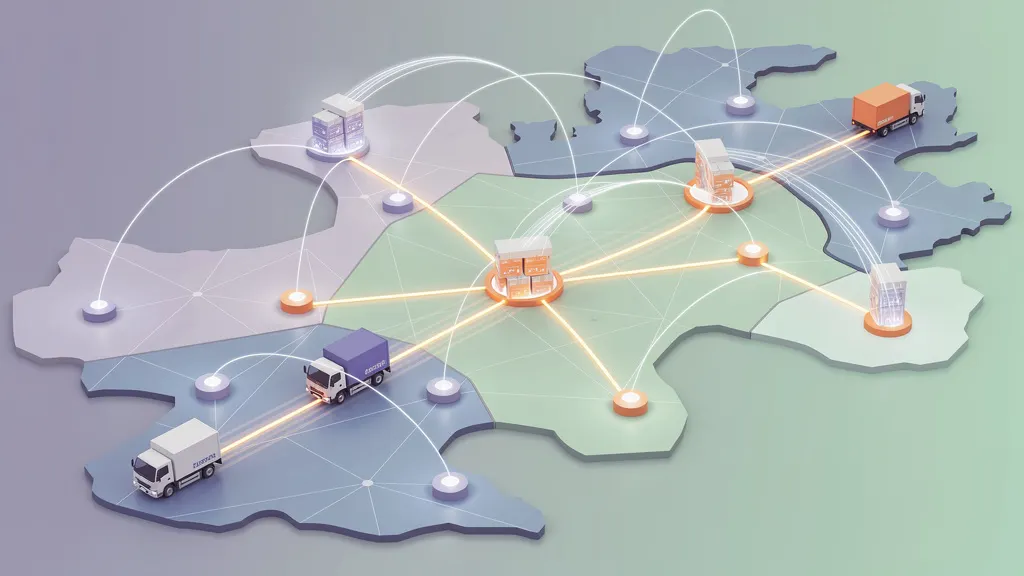
Logistics is usually split into three stages. First mile covers pickup and consolidation from origins. Last mile covers the final leg to a customer or store. Middle mile sits between them: long-haul and regional movement of consolidated freight between distribution centers, fulfillment centers, sorting hubs, and cross-docks.
Middle-mile problems have a distinctive shape:
- Hub-and-spoke structure. Demand is not uniformly distributed over a map; it concentrates at facilities whose locations were chosen years ago for reasons that have nothing to do with your algorithm.
- Consolidated but heterogeneous demand. A trailer load is not a parcel. Freight classes, pallet counts, and volume-versus-weight limits all constrain how loads can be combined.
- Temporal rhythm. Linehaul schedules are built around cutoff times, dock appointment windows, and shift boundaries. A route that is geometrically perfect but misses a dock slot is worthless.
- Resource coupling. Tractors, trailers, and drivers are separate resources with separate constraints. A driver's remaining hours can invalidate a plan that the routing layer thought was feasible.
- Cost asymmetry. The expensive decisions are usually about how many trips, how many vehicles, and how much deadhead mileage — not about the exact sequence of the final few stops.
Classical benchmark instances were largely designed for a different problem family, typically last-mile or generic capacitated routing. They are excellent for comparing algorithms on a common footing, but they can under-represent the structural features that dominate middle-mile performance. That is the gap a realistic instance generator is meant to narrow: not to replace public benchmarks, but to add a distribution of instances that looks more like what operators actually face.
What MilleMiglia Is — and What the Public Evidence Says
Based strictly on the primary source, MilleMiglia is a realistic instance generator targeted at middle-mile logistics. The title of the Google Research publication is the anchor fact here: a generator, oriented toward realism, scoped to the middle mile.
That is a narrower claim than it might first appear, and it is worth being disciplined about it. The published description does not (on the evidence available to me) establish a specific file format, a specific command-line interface, a specific package on any registry, a documented parameter schema, or published benchmark numbers. Anyone building on MilleMiglia should therefore treat the official source page as the authority for interface details, and treat this article as a guide to the surrounding workflow: environment setup, configuration thinking, harness construction, and realism validation.
The value proposition of a generator like this is reproducibility. Instead of hoping a collaborator has the same proprietary dataset you do, you share a seed, a configuration, and a version identifier — and both parties regenerate the same instances. That property is what makes results comparable across teams.
Requirements
Before installing anything, confirm you have the following. The list is deliberately conservative and reflects general tooling for this kind of research artifact.
- Python 3.10 or later. Modern scientific stacks have largely dropped older interpreters. Check the official source for the exact requirement, since that is the binding constraint.
- A virtual environment. Never install a research artifact into a system interpreter; dependency conflicts in this space are common.
- Git, to obtain the source and to record the exact commit you used.
- Core numerical libraries: NumPy and pandas for data handling, NetworkX if you want to inspect the graph structure of a generated network, Matplotlib for diagnostics.
- At least one routing solver for consuming instances. Google OR-Tools is a reasonable default; commercial solvers or custom heuristics work equally well, since the generator's output is data, not a solver interface.
- Disk and RAM headroom. Generated instance sweeps are cheap individually and surprisingly large in aggregate. A few gigabytes of free disk for instance archives is a sensible starting point.
Step-by-step installation
A warning first: the commands below are environment scaffolding, not a transcription of MilleMiglia's official install instructions. Where a repository URL or package name is required, I have left a placeholder. Take those values from the official source page.
Confirm your interpreter version before creating anything.
python3 --versionCreate and activate an isolated virtual environment. Keeping this outside your project directory avoids accidentally committing it to version control.
python3 -m venv ~/.venvs/millemiglia
source ~/.venvs/millemiglia/bin/activate
Upgrade the packaging tools. Older pip versions frequently fail on modern wheels.
python -m pip install --upgrade pip setuptools wheelSet up a working directory with separate folders for generated instances, configuration files, outputs, and logs. Separating these makes it trivial to archive an experiment later.
mkdir -p ~/work/millemiglia/{src,instances,configs,outputs,logs}
cd ~/work/millemiglia
Obtain the generator source. Replace the placeholder with the actual repository location given in the official documentation.
git clone <MILLEMIGLIA_REPO_URL> src/millemigliaRecord the exact commit. This is the version identifier you should cite alongside any results.
cd src/millemiglia && git rev-parse HEAD | tee ../../logs/commit.txtIf the artifact ships as an installable Python package, install it in editable mode so local changes take effect without reinstalling.
python -m pip install -e .Install the surrounding analysis and solver stack. These are general-purpose tools, independent of the generator itself.
python -m pip install numpy pandas networkx matplotlib
python -m pip install ortools
Freeze the resolved environment. Reproducing a benchmark requires reproducing the environment, not just the seed.
python -m pip freeze > ../../configs/requirements.lock.txtFinally, set a deterministic hash seed for the session. Python's hash randomisation is a classic source of run-to-run variation in code that iterates over sets or dictionaries.
export PYTHONHASHSEED=0Configuration: from seed to scenario
Configuration is where a generator earns or loses the word "realistic." The exact parameter schema is an interface detail you should read from the official documentation. What follows is a checklist of the dimensions a middle-mile generator typically has to expose, framed so you can map it onto whatever format MilleMiglia actually uses. Treat the YAML below as an illustrative template, not as a documented schema.
# ILLUSTRATIVE TEMPLATE — map these concepts to the real parameter names.
scenario:
  name: "metro-region-baseline"
  seed: 20260918          # reproducibility anchor
  horizon_hours: 24       # planning window

network:
  num_hubs: 8
  hub_placement: "clustered"   # not uniform random
  service_time_minutes: [20, 45]

demand:
  total_loads: 400
  size_distribution: "lognormal"
  temporal_profile: "peaked"   # cutoffs and shift starts

fleet:
  vehicle_types: ["van", "straight_truck", "tractor_trailer"]
  capacity_units: "pallets"
  max_drive_hours: 11
  depot_assignment: "fixed"

costs:
  per_mile: 1.0
  per_hour: 1.0
  fixed_dispatch: 150.0
Three principles matter more than any individual field:
Seed everything. A generator that is not fully deterministic given a seed cannot support reproducible research. Record the seed alongside the instance name, always.
Parameterise distributions, not single values. Real operations vary. A generator that emits one fixed demand profile produces one kind of instance. Distributions over demand sizes, service times, and arrival patterns let you sweep across regimes and find where an algorithm's advantage disappears.
Separate structural realism from statistical realism. Structural realism means the network topology looks like a hub-and-spoke system — clustered facilities, plausible inter-hub distances, asymmetry between lanes. Statistical realism means the marginal distributions of loads, times, and costs match operational data. A generator can have one without the other, and it is worth testing them independently.
Usage examples
Generating an instance set
The typical pattern is a sweep over seeds with a fixed configuration, producing one instance file per seed. The invocation below uses a placeholder entry point; substitute the real one.
cd ~/work/millemiglia
for seed in 1 2 3 4 5; do
  python -m millemiglia.generate \
    --config configs/baseline.yaml \
    --seed "$seed" \
    --out "instances/baseline_${seed}.json" \
    2>> "logs/generate_${seed}.err"
done
The loop writes each seed's instance to its own file and captures stderr separately, which makes partial failures obvious rather than silent.
Validating the output schema
Before feeding anything into a solver, confirm the files are complete and internally consistent. The field names below are illustrative; adapt them to the actual schema.
import json
from pathlib import Path

REQUIRED = {"seed", "hubs", "loads", "vehicles"}

def validate(path: Path) -> bool:
    try:
        data = json.loads(path.read_text())
    except json.JSONDecodeError:
        print(f"{path.name}: malformed JSON")
        return False

    missing = REQUIRED - set(data)
    if missing:
        print(f"{path.name}: missing {sorted(missing)}")
        return False

    total_capacity = sum(v["capacity"] for v in data["vehicles"])
    total_demand = sum(l["size"] for l in data["loads"])
    if total_demand > total_capacity:
        print(f"{path.name}: infeasible by construction "
              f"({total_demand} > {total_capacity})")
        return False

    return True

good = [p for p in sorted(Path("instances").glob("*.json")) if validate(p)]
print(f"{len(good)} instances passed validation")
The capacity check is cheap and catches the most common category of generator bug: instances that no algorithm could ever solve.
Comparing generated instances against operational data
This is the realism test that matters most. Export a small set of per-route or per-lane features from both your generated instances and a reference dataset, then compare distributions rather than means alone.
import pandas as pd

generated = pd.read_csv("outputs/generated_lane_features.csv")
reference = pd.read_csv("data/reference_lane_features.csv")

for column in ["stops_per_route", "lane_distance_km", "load_utilisation"]:
    print(column)
    print("  generated:", generated[column].describe()[["mean", "std"]].to_dict())
    print("  reference:", reference[column].describe()[["mean", "std"]].to_dict())
Matching means with mismatched standard deviations is a red flag: it usually means the generator is producing a plausible average case and an implausible spread. Solvers are frequently more sensitive to variance than to central tendency.
Stress-testing a solver across regimes
Once you have an instance set, the natural experiment is a regime sweep. Rather than one number, report a curve.
import subprocess, time, json
from pathlib import Path

results = []
for inst in sorted(Path("instances").glob("baseline_*.json")):
    start = time.perf_counter()
    proc = subprocess.run(
        ["python", "-m", "your_solver", "--instance", str(inst),
         "--time-limit", "60"],
        capture_output=True, text=True,
    )
    elapsed = time.perf_counter() - start
    results.append({
        "instance": inst.name,
        "seconds": round(elapsed, 3),
        "ok": proc.returncode == 0,
    })

Path("outputs/solver_sweep.json").write_text(json.dumps(results, indent=2))
Run this at several values of the demand-scale parameter and you get a scaling curve — far more informative than a single aggregate score, and much harder to game.
Validating Realism Before You Trust a Benchmark
A generator claiming realism invites a specific question: realistic according to what? Four checks are worth institutionalising.
Structural check. Plot the hub network. Are facilities clustered along plausible corridors, or scattered as if by uniform sampling? Uniformity is the default that realism has to beat.
Distributional check. Compare marginals for demand size, service time, and lane distance against reference data. Use quantile plots, not just summary statistics.
Constraint check. Verify that tight constraints actually bind. If driver-hour limits never activate, the generator is not exercising the part of the problem that makes middle-mile hard.
Discriminative check. Confirm the instances separate algorithms. A benchmark on which every reasonable method scores identically is measuring noise. Conversely, instances that are all trivially easy or all infeasible carry no signal either.
A generator that passes structural and distributional checks but fails the discriminative one is a faithful simulation of the wrong thing — an important failure mode to watch for.
Where the Evidence Ends
Honesty about the boundary is part of the technical content. The verified facts are narrow: Google Research has published a realistic instance generator for middle-mile logistics, under the title "MilleMiglia: A realistic instance generator for middle-mile logistics," at the URL cited above, with the source record timestamped 2026-09-18T17:46:09.000Z.
Everything else in this article — the parameter template, the harness code, the validation checklist, the requirement list — is standard engineering practice for working with any instance generator in this domain. It is offered as scaffolding to adapt, not as documentation of MilleMiglia's interface.
Two practical consequences follow. First, treat the official source as authoritative for the interface; do not propagate placeholder commands as if they were real. Second, when you publish results, cite the generator version and seed explicitly, because that is what makes the comparison reproducible.
Conclusion
MilleMiglia addresses a real methodological gap: middle-mile optimization has been benchmarked largely on instances built for other problem families. A generator aimed at realistic middle-mile instances gives researchers a way to test algorithms against hub-and-spoke structure, consolidated heterogeneous demand, and operational time constraints — and, crucially, to do so reproducibly by sharing seeds rather than datasets.
The practical workflow is unglamorous but effective. Isolate the environment, pin the commit, seed everything, sweep configurations rather than single points, and validate realism on four axes: structure, distribution, constraint binding, and discriminative power. The most valuable output of a generator is not any single instance but the curve your solver draws across a family of them — and the honest reporting of where that curve flattens.